
AGI vs. AI: Key differences and how to evaluate AGI claims
Compare AI and AGI, explore competing definitions and learn how to assess benchmarks and claims of general intelligence.
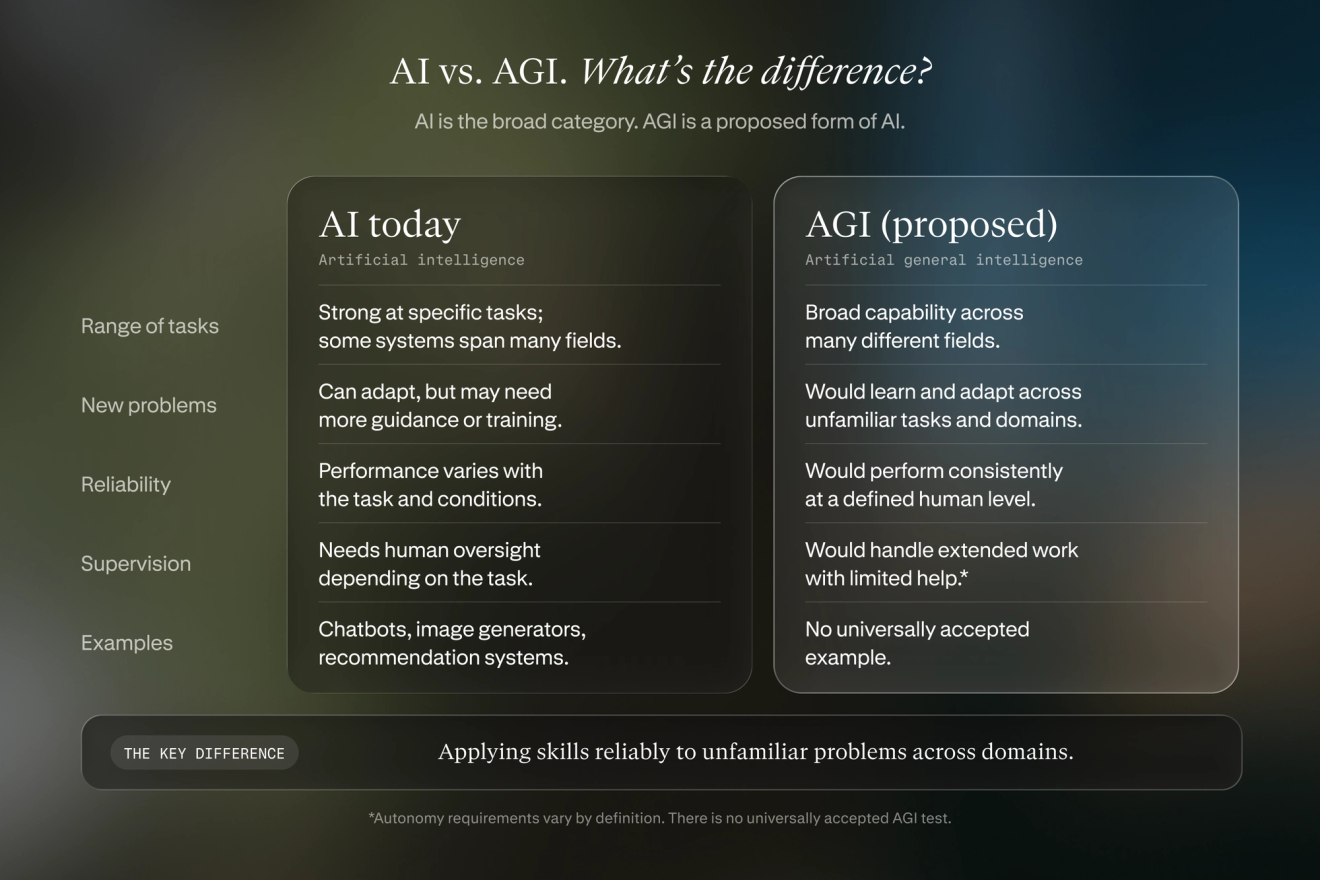
Artificial intelligence (AI) covers a broad category of systems that perform tasks associated with intelligence. Artificial general intelligence (AGI) is a theoretical form of AI that applies machine intelligence at a more or less human level across different domains. AI already performs tasks such as:
- Writing software
- Analyzing images
- Conducting research
- Completing knowledge and creative work with a wide range of digital tools
But its abilities remain uneven depending on how the AI was trained, prompted, equipped, and supervised.
AGI would apply intelligence reliably across unfamiliar tasks and domains. However, researchers disagree on what would make an AI system an AGI and there is no universally accepted test.
Imagine asking an AI assistant to tackle a problem it wasn’t specifically trained to solve. An AGI system would autonomously figure out what it needs to learn, apply knowledge from other areas, and adapt if its first approach fails. That’s AGI, and it’s something AI platforms still can’t do as of October 2026.
Researchers have different ways of evaluating that capability by looking at things like learning efficiency, cognitive breadth, and autonomous work.
AGI vs. AI at a glance
AI is the broad field of creating systems that perform tasks associated with intelligence. People commonly use AI models and tools for business, academia, and recreation.
There are a variety of AI model including:
- Large language models (LLMs): Models trained on large collections of text that predict what words should statistically come next.
- Text-to-image models: Models that turn text queries into images based on patterns learned in training.
- Deep learning models: Models that learn patterns from data by using many layers of connected processing units.
AGI is a hypothetical kind of AI that transfers knowledge across domains and adapts to unfamiliar problems. The big difference is that it would perform many work and recreational tasks like running a business or playing an open-world video game at a specified level of human ability.
Comparing current AI and hypothetical AGI
Dimension | AI in use today | AGI as commonly defined |
Scope | Performs specific tasks or a wide range of tasks with uneven capability | Generalizes across a broad range of unfamiliar tasks and domains |
Learning and adaptation | Adapts through training, instructions, examples, or tools | Adapts to unfamiliar problems without task-specific retraining |
Transfer | Applies knowledge across domains, but transfer is uneven | Transfers knowledge and ideas across domains more consistently |
Autonomy | Varies by system and task; may require human direction or intervention | Completes extended work with limited supervision under autonomy-based definitions |
Reliability | Can be highly capable but inconsistent across conditions | Would meet a pre-defined human-performance threshold across a wide range of tasks and conditions |
Status | Widely deployed | Proposed category with claims of achievement remaining contested |
Examples | Language models, recommendation systems, image models, autonomous agents | No universally accepted example |
What AI means today
Broadly speaking, there are three kinds of AI systems: narrow, generative, and agentic. Narrow AI might check documents for grammar and spelling, generative AI might write a story, and agentic AI might send coworkers emails with user approval.
Narrow AI: what’s actually deployed
Narrow AI systems perform best on specific tasks.
Common narrow AI use cases include recommendation systems, fraud detection, image recognition, and game-playing systems. They typically don’t perform well beyond their core task.
Generative AI is a subset, not a step toward AGI by itself
Generative AI systems generate text, images, audio, video, code, and other content based on inputs we give them. The term “generative AI” describes what the system produces, not whether the AI is an AGI.
Popular generative AI systems include the following:
- Perplexity
- Gemini
- Claude
Agentic AI ≠ AGI
Agentic AI systems autonomously plan and take actions towards goals while using tools and software. While the idea of agency matters in several AGI definitions, agentic AI doesn’t meet the criteria for AGI yet. Agentic systems can’t work indefinitely on their own or learn new topics that they haven’t been trained for yet.
The current wave of AI personal assistants falls under the agentic AI category. Systems performing autonomous tasks like using software and websites, analyzing spreadsheets, and drafting emails don’t count as AGI.
What AGI means and why definitions differ
Researchers and AI developers propose different standards for both what AGI includes and measuring it. Some emphasize economically valuable work while others prioritize learning unfamiliar tasks or demonstrating broad cognitive abilities.
Why AGI definitions differ
Different definitions of AGI give different weight to breadth, human-level performance, learning efficiency, and autonomy.
AGI definition | What counts as AGI? | Primary source |
Automating knowledge work at expert level | AI that automates the vast majority of non-physical work at expert level | |
Learning efficiency | Matches human efficiency in acquiring skills for unfamiliar tasks | |
Cognitive breadth | Matches or exceeds a well-educated adult’s cognitive versatility and proficiency across areas like memory retrieval, reasoning, and knowledge | |
Performance and generality | Broad capability measured at progressive performance levels, including “Competent AGI” at least at the 50th percentile of skilled adults with relevant skills | |
Workplace autonomy | A system that performs extended, end-to-end work with limited human intervention | |
Breadth and depth | Expert-level depth in some areas combined with competence across a broad range of different tasks |
These different definitions mean that there’s real disagreement among engineers, practitioners, business leaders, and regulators about what AGI actually is. When a lab or organization claims they achieved AGI, keep in mind what definition they’re using, what evidence supports it, and which capabilities that evidence leaves untested.
AGI doesn’t require consciousness or a body
The different definitions for AGI emphasize whether an AI can learn, solve unfamiliar problems, and apply skills across different tasks. DeepMind’s Levels of AGI framework looks at those capabilities without considering if an AI could ever be conscious or perform physical tasks. A system that achieves AGI doesn’t require anything resembling consciousness, feelings, or even thinking like a human.
What the AGI tests say now
There are a number of different tests currently being run as of October 2026 to see if any AI systems have achieved AGI.
Recent results show progress on some capabilities and limitations on others.
AGI standard | Criteria | Relevant test or evidence | Latest verified result | What the result does and doesn’t show |
Automating knowledge work at expert level | Quality across real-life occupational tasks | Remote Labor Index (RLI) | As of October 9, 2026, Claude Opus 5.5 leads the RLI leaderboard at 21.3% full automation on evaluated freelance projects | Broad usefulness across real-life occupational tasks, but not whole-job competence |
Learning efficiency | Skill acquisition for novel tasks | As of October 14, 2026, GPT-6.1 Sol Semi-Private scores are 98.5% on v1/xhigh and 94.2% v2/max. | Substantial progress in learning within the benchmark rather than proof of general, human-like learning ability | |
Cognitive breadth | Performance across 10 different cognitive domains | OpenAI GPT-5 received an estimated score of 57/100 in 2025 | GPT-5 demonstrated strong language and mathematical performance but major gaps in memory and other areas | |
Performance and generality | Breadth plus a defined human- performance percentile | No generally agreed standard result | DeepMind’s Levels of AGI framework describes how AGI would behave but doesn’t offer benchmarks | |
Workplace autonomy | Unsupervised ownership of extended work periods | GDPval, SWE- bench Pro, and autonomy evidence | Model Evaluation and Threat Research (METR’s) September 2026 evaluation of Claude Opus 5.5 found improvements in research and coding-related tasks, but continuing weaknesses in other areas | Current systems struggle with managing ambiguity, changing priorities, and flagging and correcting their mistakes over time |
Human-like conversation | Whether evaluators can distinguish a system from a person | Three-party Turing test | Jones and Bergen conducted a 15-minute test published in May 2026 in which persona-prompted GPT-5 was selected as the human 59.3% of the time, and Llama-3.1-405B 55.6% of the time | Jones and Bergen’s test showed convincing human-like conversation under controlled conditions but didn’t establish general intelligence or an ability to pass as human in every setting. |
Benchmark results last updated October 14, 2026
Current AIs excel at some tasks and struggle with others
Current AI systems meet or exceed human performance in certain areas. However, their capabilities remain uneven across most other areas.
Capability | Evidence | What the results don’t show |
Mathematical reasoning | Gemini with Deep Think achieving gold-medal standard at the International Mathematical Olympiad | Reliable reasoning across a range of unfamiliar problems |
Software engineering | Claude 4.5 Opus February 2026 SWE-bench Verified comparison | AI independently doing all the tasks of a software engineer’s job |
Learning unfamiliar tasks | GPT-6 Astra on the ARC Prize September 2, 2026 results record | Same learning capability across different tools and setups |
Visual interpretation | Claude Opus 5.5 Max achieves 77.2% on the ClockBench AI leaderboard | AI interpreting images just as well or better than humans |
Physical task execution | Low full-task completions on Stanford’s BEHAVIOR-1K benchmark for robots completing physical tasks | Robots reliably completing human-level household tasks |
Why benchmark results age quickly
AI benchmark results age rapidly and past performance doesn’t equal current capability.
The way benchmarks are judged changes over time, too. Judges sometimes change evaluation rules and test conditions. For instance, in April 2026, the ARC Prize changed ARC-AGI-3’s human baseline from the second-best player to the median player per level.
ARC-AGI-2 and ARC-AGI-3 measure different things and their scores aren’t directly comparable.
ARC-AGI-2 reports accuracy and cost while ARC-AGI-3 measures if AI can complete interactive tasks and how complicated it is for the AI. Look at what LLMs demonstrated about their capabilities under those conditions, and not just how high the LLM scored.
Is ChatGPT AGI? The answer depends on which definition you use
ChatGPT doesn’t qualify as AGI as of October 2026 in terms of breadth-and-depth, workplace autonomy, and learning efficiency. IBM describes current LLMs as falling short of AGI altogether.
While Chen et al. argue that current frontier language models show general intelligence through breadth across domains, this position isn’t generally accepted.
OpenAI says GPT-6 Astra scores 99.9% on ARC-AGI-3, but its evaluations use specific settings and may differ from production ChatGPT. This is a claim about a specific model and evaluation setup.
Instead of arguing whether an LLM achieved AGI, it’s more useful to examine what a particular claim means. This means looking at which model was evaluated, which tools it could use, how much humans helped, and which definition performance was measured against. Differentiating between them keeps impressive performance results separate from big claims about achieving general intelligence.
AGI examples: why honest lists are short
Imagine an autonomous small-business assistant that achieved AGI. The assistant works on its own without human assistance, understands unfamiliar work, connects information across departments, and independently adapts when circumstances change.
A user could ask this assistant for help opening a second retail location. The AGI-capable AI service would move between bookkeeping, project management, and business development, learn unfamiliar software, and investigate local requirements all on its own.
If a supplier dropped out, the AI could autonomously assess alternatives and forecast new costs. That transferable problem-solving ability is the key distinguishing feature for AGI.
In comparison, many AI systems that meet or exceed human capabilities in the present day only qualify as narrow AI. Exceptional success at playing chess or predicting protein structures doesn’t translate into broad competence in other fields.
How to check AGI claims in five minutes
A preliminary check can reveal problems with AGI claims. Quick checks won’t settle whether a system or model qualifies as AGI, but they uncover missing information, unsupported conclusions, or results that need further research.
Because different organizations have different criteria for AGI and their own interests in setting benchmarks, being critical is essential.
This table lists seven different checks for assessing AGI claims.
Check | Red flag | Fast verification |
Which definition is being used? | Claim doesn’t clearly define AGI | Look for a threshold that clearly measures breadth, autonomy, human performance, or learning efficiency |
Which test maps to that definition? | Benchmark is named without explaining what it’s measuring | Read the benchmark description |
Which model was tested, when, and with what score? | Claim gives a score without accompanying information | Refer to the live results table |
Who conducted the evaluation? | Vendor conducted their own evaluation without outside evaluation | Look for third-party or benchmark owner verification |
What tools and compute are allowed? | Results omit cost, tools, retries, or test-time adaptation | Read the evaluation conditions |
How much human assistance did the AI receive? | Polished demos are described as autonomous work | Look for end-to-end completion and recovery without intervention |
Would another definition change the conclusion? | Meeting one proposed standard is presented as a system achieving AGI | Compare evidence with another framework and find requirements that are still untested |
Checking AGI claims is a similar process to spotting AI hallucinations.
Suppose a company says its AI “matches human intelligence” because it scores highly on a reasoning benchmark. Even if the score is independently verified, the score doesn’t establish that the AI learns unfamiliar tasks, works across domains, or completes extended work without human assistance. If those capabilities weren’t tested, the case for that AI achieving AGI becomes much weaker.
What the AGI distinction changes today
Users will use AI tools whether or not they’re called AGI. Organizations don't need to decide whether a tool is AGI before using it. But they should establish whether it performs their tasks they need done reliably and within acceptable limits.
Before rolling out a tool, organizations should answer four questions:
- Which tasks an AI system performs reliably and which it doesn’t
- Which data and tools the AI system needs access to
- How much supervision the AI system needs
- How to detect potential AI failures
A practical AI integration plan should define success metrics, test representative workflows, and specify when humans are needed in the loop. Managers should be more vigorous in their verification as systems take on more tasks with more autonomy. Strong benchmark scores don't remove the need for human review.
Frequently asked questions
What is the main difference between AI and AGI?
The main difference between AI and AGI is that AI is the broad field of creating systems that perform intelligence-related tasks. AGI is a proposed form of AI that would reliably transfer knowledge and adapt to unfamiliar problems across different domains at human-like levels. AGI can more broadly and reliably apply its capabilities compared to regular AI.
Is ChatGPT AGI?
As of October 2026, there is no consensus that ChatGPT qualifies as AGI. Some researchers argue that frontier language models already demonstrate general intelligence through broad capabilities and strong performance across domains. ChatGPT doesn’t meet other definitions and there is no universally accepted pass-or-fail test.
Does AGI exist yet?
There is no consensus on whether AGI exists yet. No current system meets most AGI definitions, but some researchers argue that current LLMs meet reasonable breadth-and-depth criteria.
Does AGI require consciousness?
AGI doesn’t require consciousness under capability-based frameworks such as Google DeepMind’s Levels of AGI. Consciousness and intelligence are separate questions and commonly accepted definitions for AGI center around what systems can do.
How would we know if AGI existed?
Credible AGI claims include a definition, a matching test, a human baseline, and evaluation conditions. The claimant would provide evidence showing that the system meets the criteria.
What is the difference between AGI and ASI?
AGI generally refers to broad intelligence at a defined human level. Artificial superintelligence (ASI) is a hypothetical system that exceeds human ability across most or all relevant
cognitive domains.
Will scaling large language models lead to AGI?
There is disagreement on whether scaling large language models will lead to AGI. Some researchers believe that increasing scale and multimodal training could be a route to broader intelligence, while others argue that current architectures lack key ingredients such as world models, efficient learning, persistent memory, or reliable planning.